

- What data the agent can access: which tables and columns of your connection it may query.
- What that data means: table and column descriptions, and which columns hold values worth filtering by.
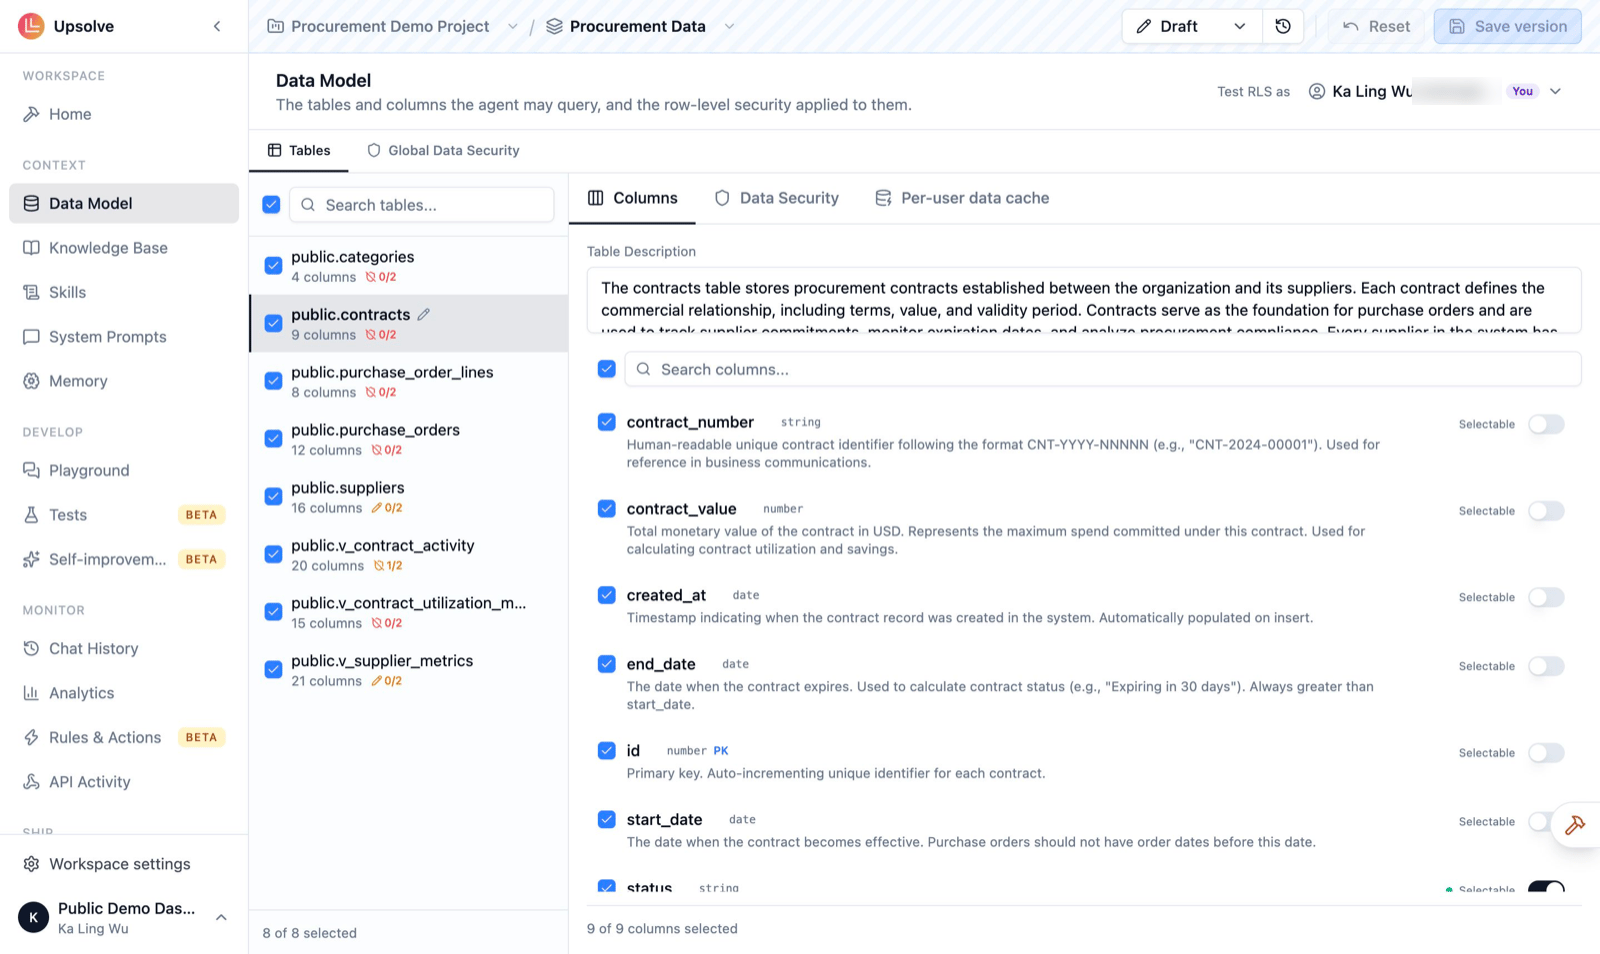
Select tables and columns
Not every table in your database is relevant to every question your agent will answer. Narrowing the schema to what matters reduces ambiguity, improves accuracy, and keeps the agent away from data it shouldn’t touch.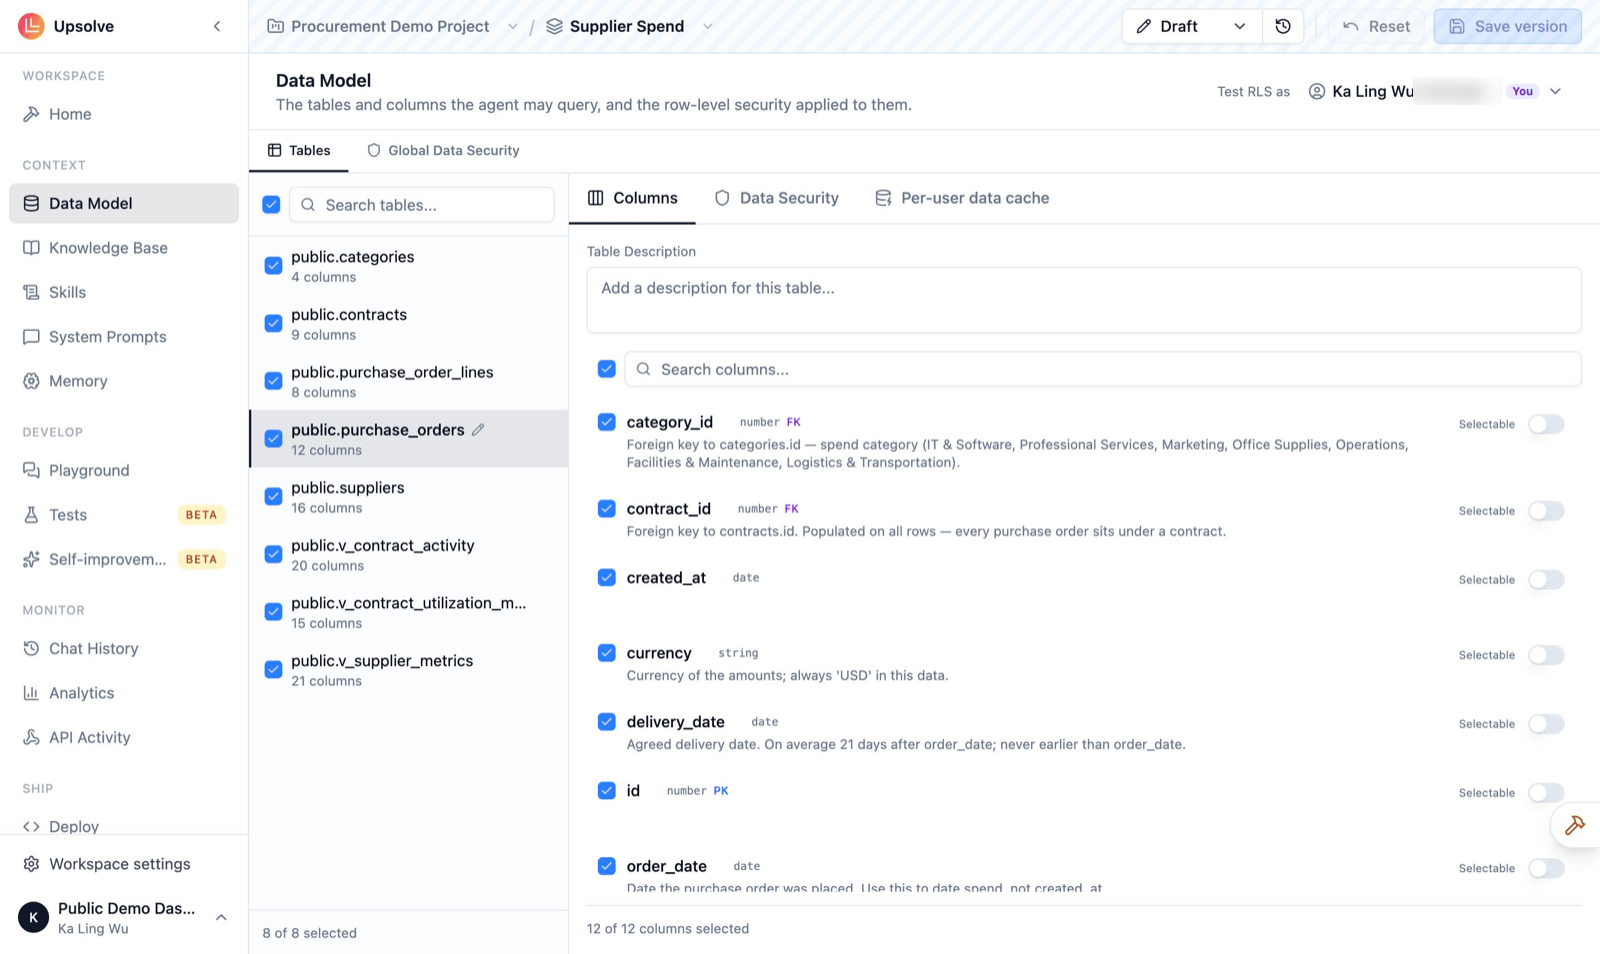
- Open the workspace’s Data Model page, on the Tables tab. Every table from the connection is listed and selected by default.
- Uncheck the tables that aren’t relevant to what you’re building.
- Expand a table and uncheck any columns that are unnecessary, sensitive, or likely to confuse the agent.
Less is more. An agent scoped to 5 relevant tables with clear descriptions will significantly outperform one with access to 50 tables it has to guess about.
Describe tables and columns
Descriptions are how you encode institutional knowledge directly into the schema. The agent reads them when it writes SQL: they tell it what your data actually means, not just what it’s called.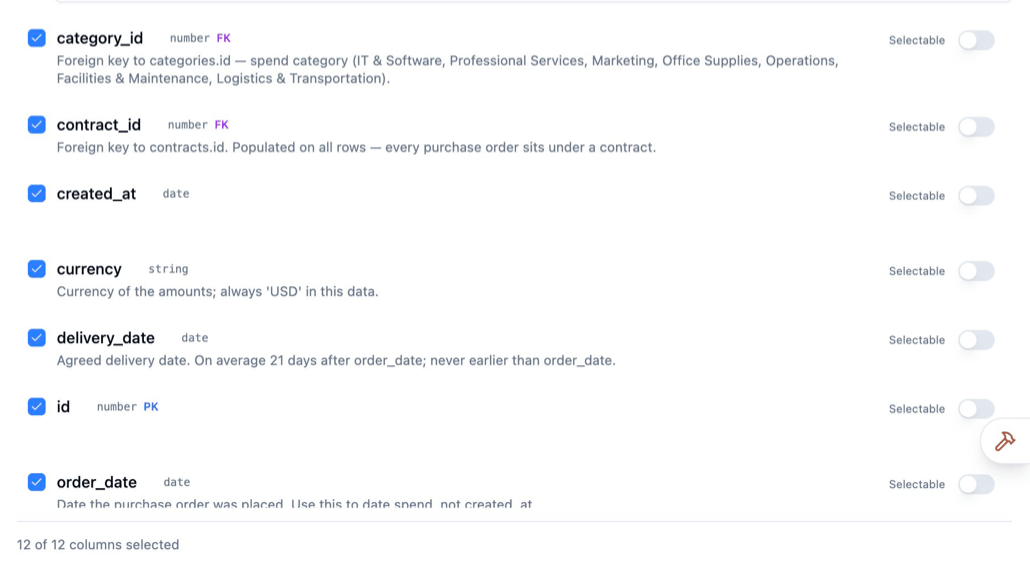
contact_name→ “Name of the customer’s point of contact for this order”owner_name→ “Name of the sales rep (seller) who owns this account”arr→ “Annual Recurring Revenue in USD, calculated as MRR × 12. Excludes one-time fees.”
Mark columns as selectable
The Selectable toggle lets the agent look up a column’s distinct values when it answers.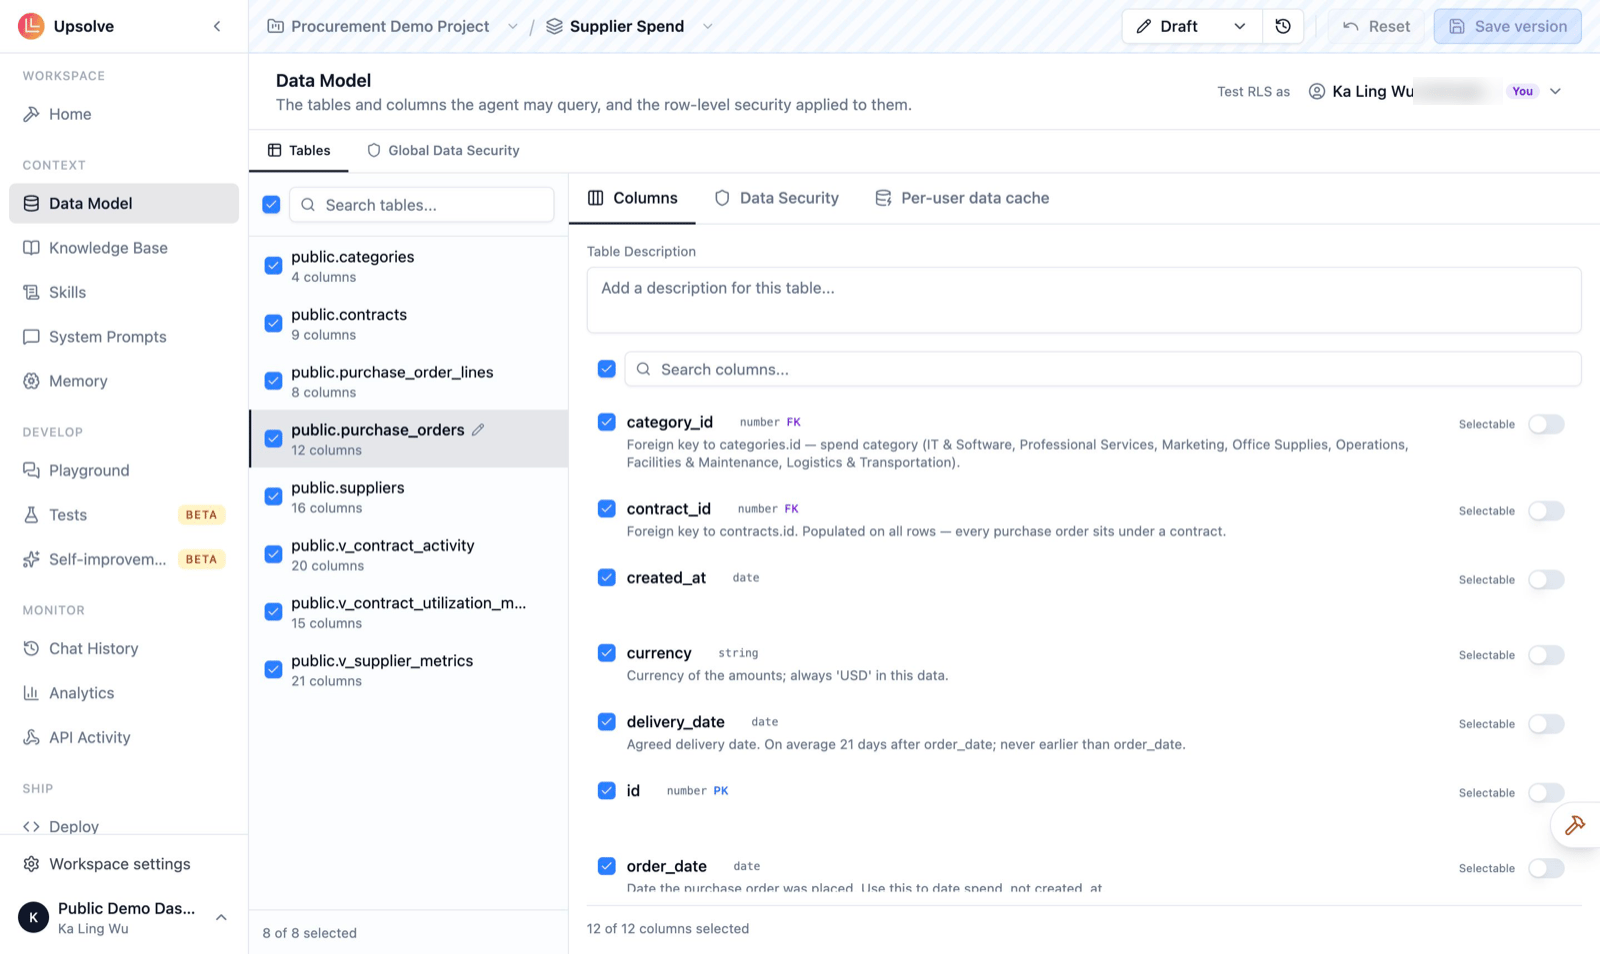
- Filtering on real values. It knows that
regioncontains “North America”, “EMEA” and “APAC” before it writes aWHEREclause, so it filters on real values rather than guessing at spellings. - Matching loose references. It can search a column’s values to find the exact entry a user referred to loosely, matching “acme” to the
customer_namevalue “Acme Corp (US)”.
Beyond the schema
Descriptions cover what your data means. Context that isn’t about any one column (business policies, company background, definitions of terms people use loosely, known caveats about the data) belongs in the Knowledge Base. See Encode Your Context for where each kind of knowledge goes.Save a version
Changes to the data model autosave to the workspace’s draft; there is no separate save step. Your users keep getting the version in production until you save a new version and promote it, which ships the schema together with the rest of the agent’s context. See Workspaces.When your database changes
If your database schema changes:- Open the workspace’s Settings and go to the Connection tab.
- Refresh the connection’s schema.
- New tables and columns appear in the Data Model, ready to select. Tables and columns that disappeared show warnings.
Next steps
Data Governance
Control which rows each user can see, and how much data reaches the AI.
Encode Your Context
Layer prompts, skills and knowledge on top of the schema.
Knowledge Base
Reference documents the agent searches to interpret your terms.
Builder Agent
Have the Builder agent write your descriptions.